Qiaolin Wang
Building Audio General Intelligence
Researcher at Bland | qw2443@columbia.edu
I am Qiaolin Wang, a researcher at Bland, where I work on expressive ASR, TTS, post-training, and speech-to-speech systems. I received my M.S. in Electrical Engineering from Columbia University, advised by Professor Nima Mesgarani.
I am passionate about building models that can Perceive, Reason, and Speak as naturally as humans do. My research has examined the fundamental capabilities of Large Audio Language Models (LALMs): their internal representations of syntax and context (EMNLP 2025, SAC Highlight), their capacity for cross-modal reasoning (ICASSP 2026), and their contextual and cultural understanding of audio-visual media (COLM 2026).
Before Columbia, I earned my B.Eng. in Computer Science from Wuhan University and was a research intern at Wiz.AI, where I built a state-of-the-art speech emotion recognition LLM.
News
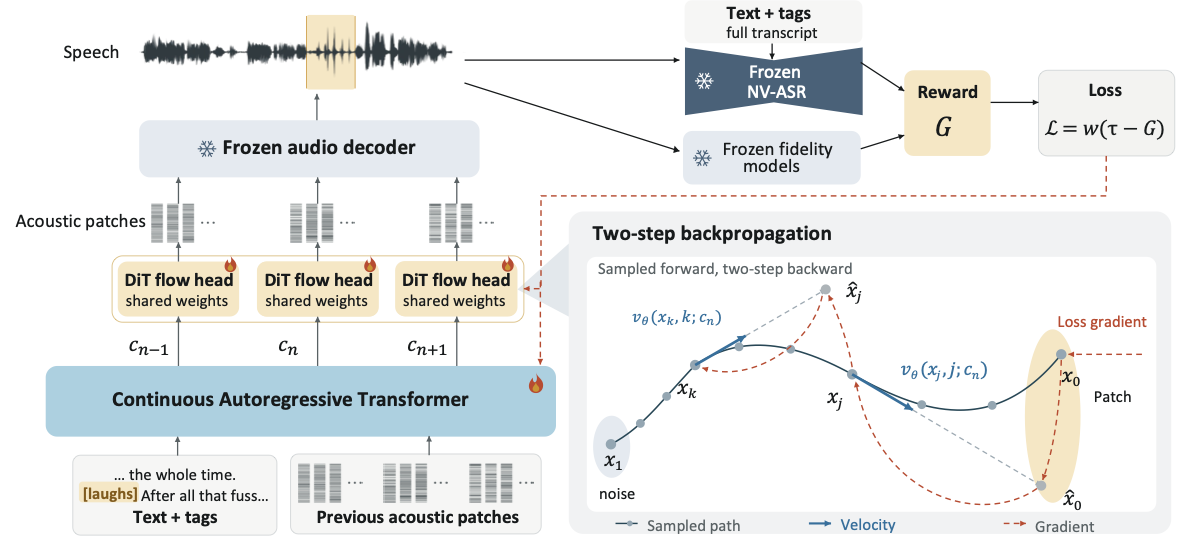
| Sep 28, 2026 | 📄 NVAlign is now on arXiv! Direct-gradient post-training that improves non-verbal control in continuous autoregressive flow-matching TTS. Audio samples here. |
|---|---|
| Jul 08, 2026 | 🎉 AVMeme Exam was accepted to COLM 2026! Explore the benchmark. |
| Apr 06, 2026 | 🚀 I joined Bland as a researcher, working on expressive ASR, TTS, post-training, and speech-to-speech systems. |
| Jan 25, 2026 | 📄 AVMeme Exam is now on arXiv! A multimodal, multilingual, multicultural benchmark for LLMs’ contextual and cultural knowledge. Project page here. |
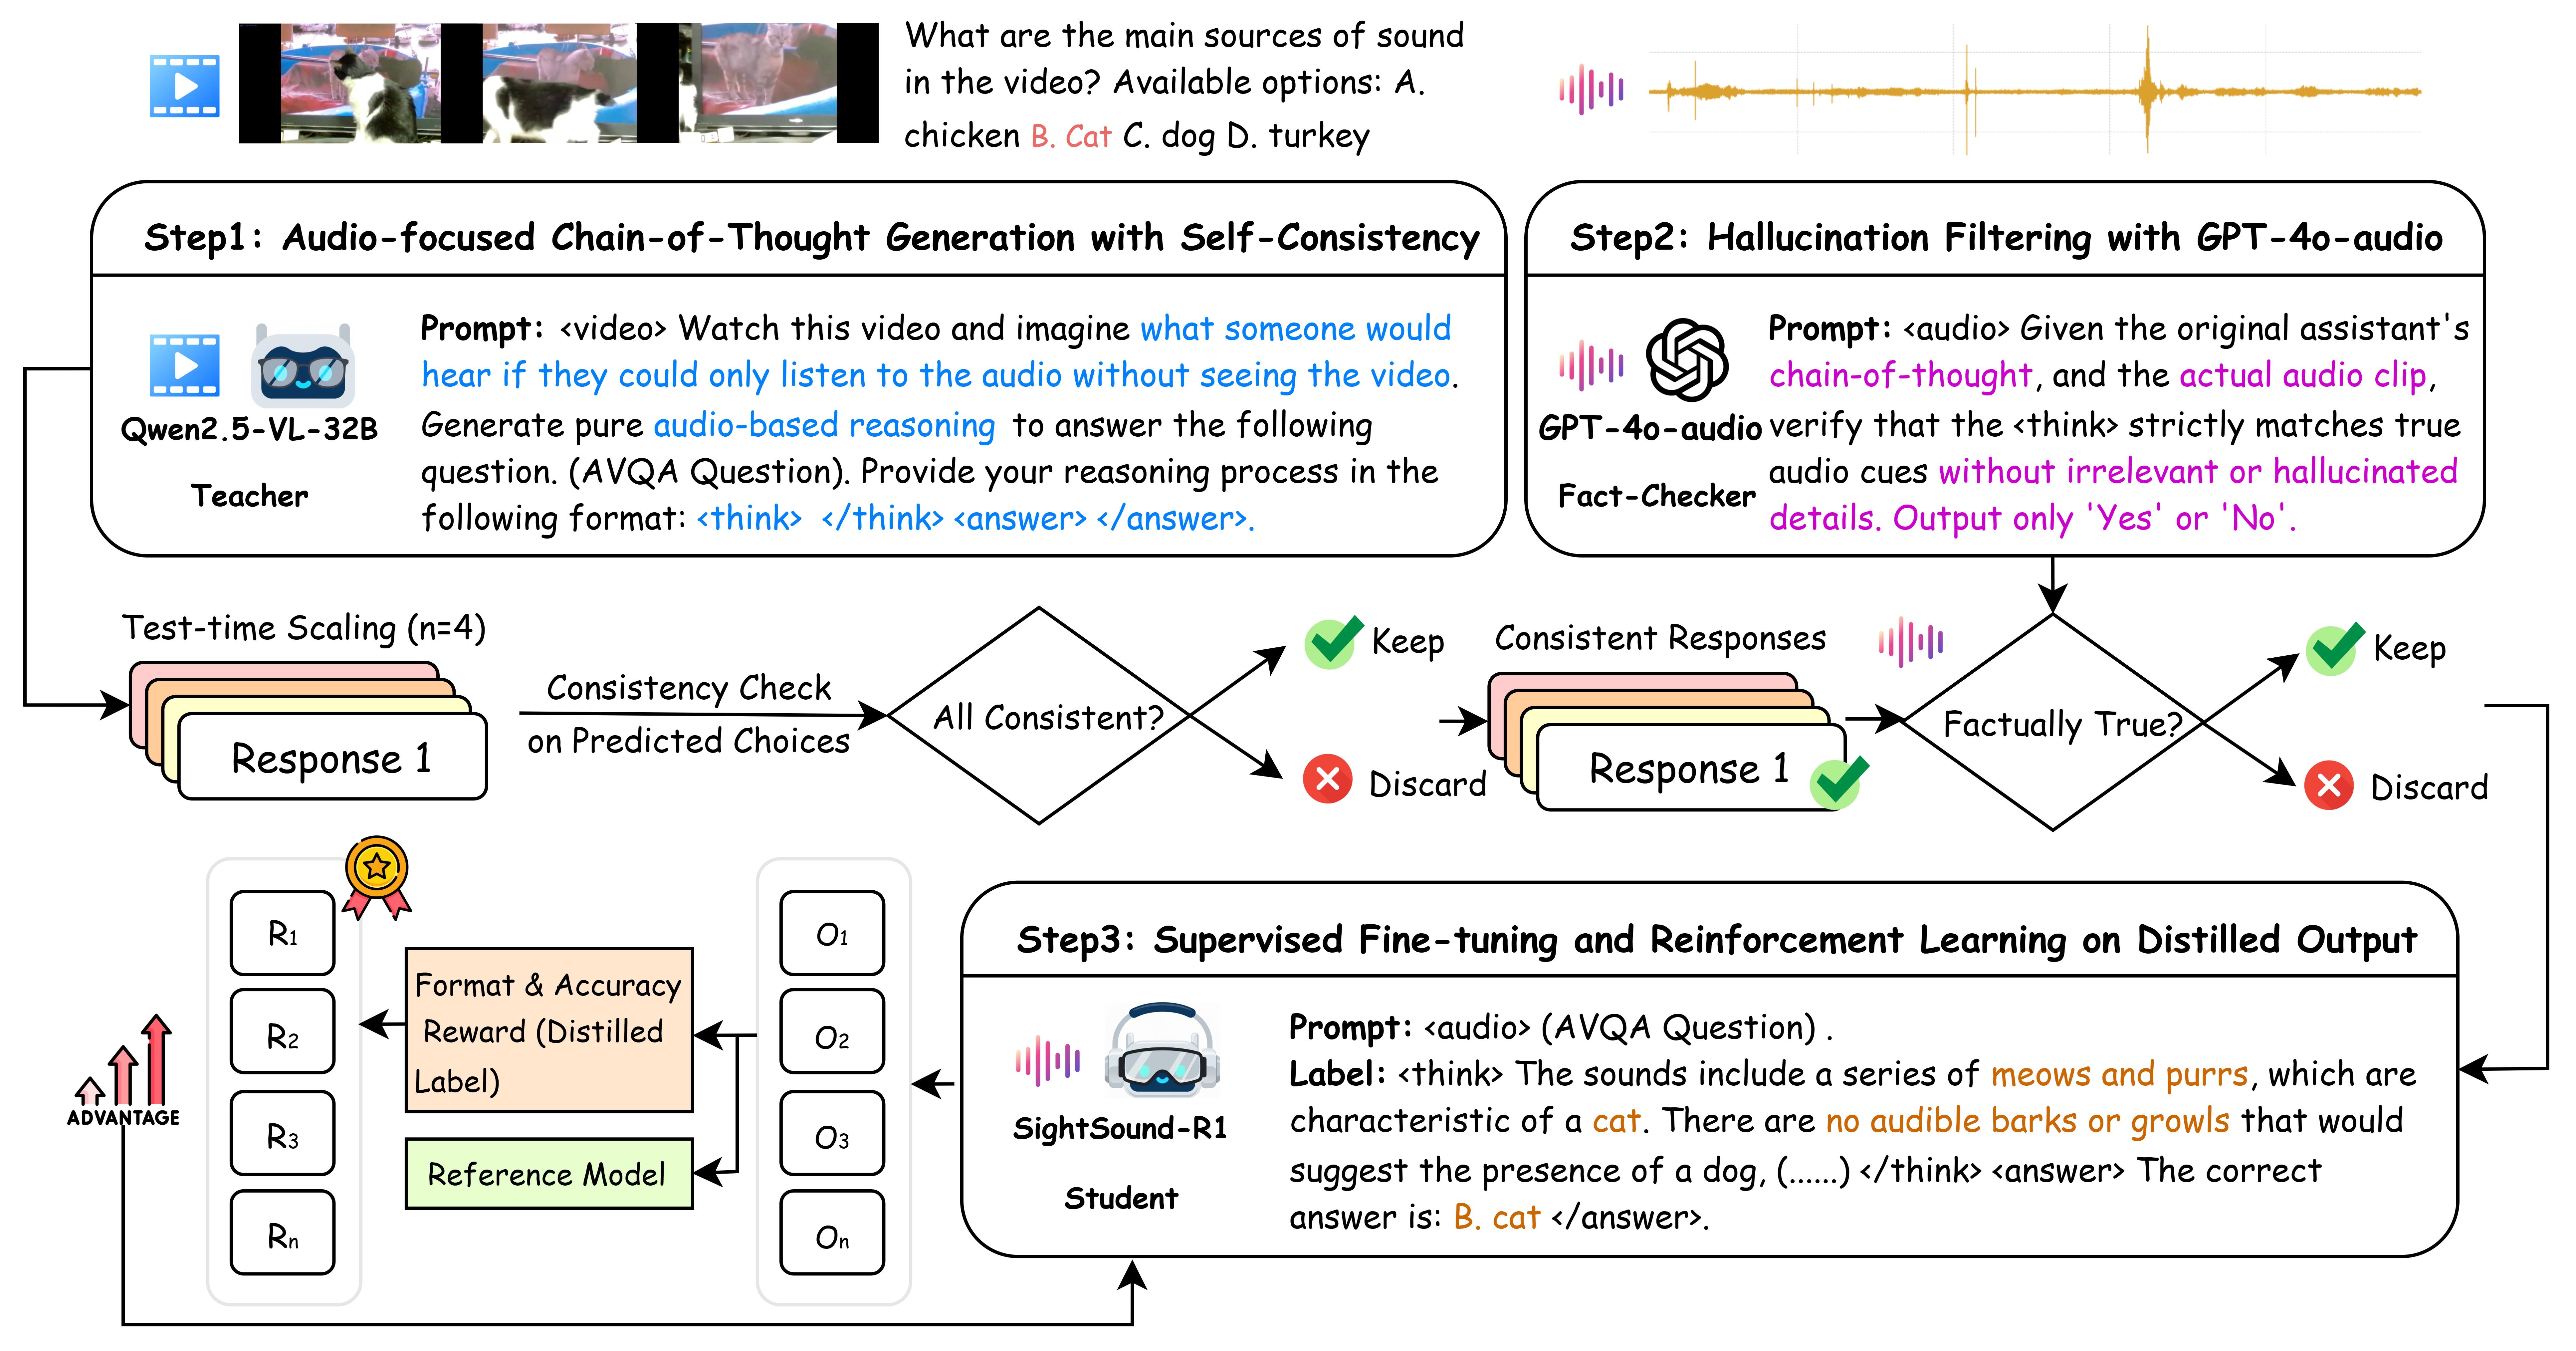
| Jan 17, 2026 | 🎉 SightSound-R1 was accepted to ICASSP 2026! Read it on IEEE Xplore or arXiv. |
| Nov 10, 2025 | 🏆 Our paper was awarded EMNLP SAC Highlight! |
| Nov 07, 2025 | 🎤 I will be presenting our work at the SANE 2025 workshop at Google NYC! |
| Sep 19, 2025 | 📄 SightSound-R1 is now available on arXiv! In this work, we propose a framework to transfer reasoning from VLMs to LALMs. |
| Aug 07, 2025 | 🎉 Thrilled that our paper was accepted for an oral presentation at EMNLP 2025! |
Selected Publications
- EMNLP
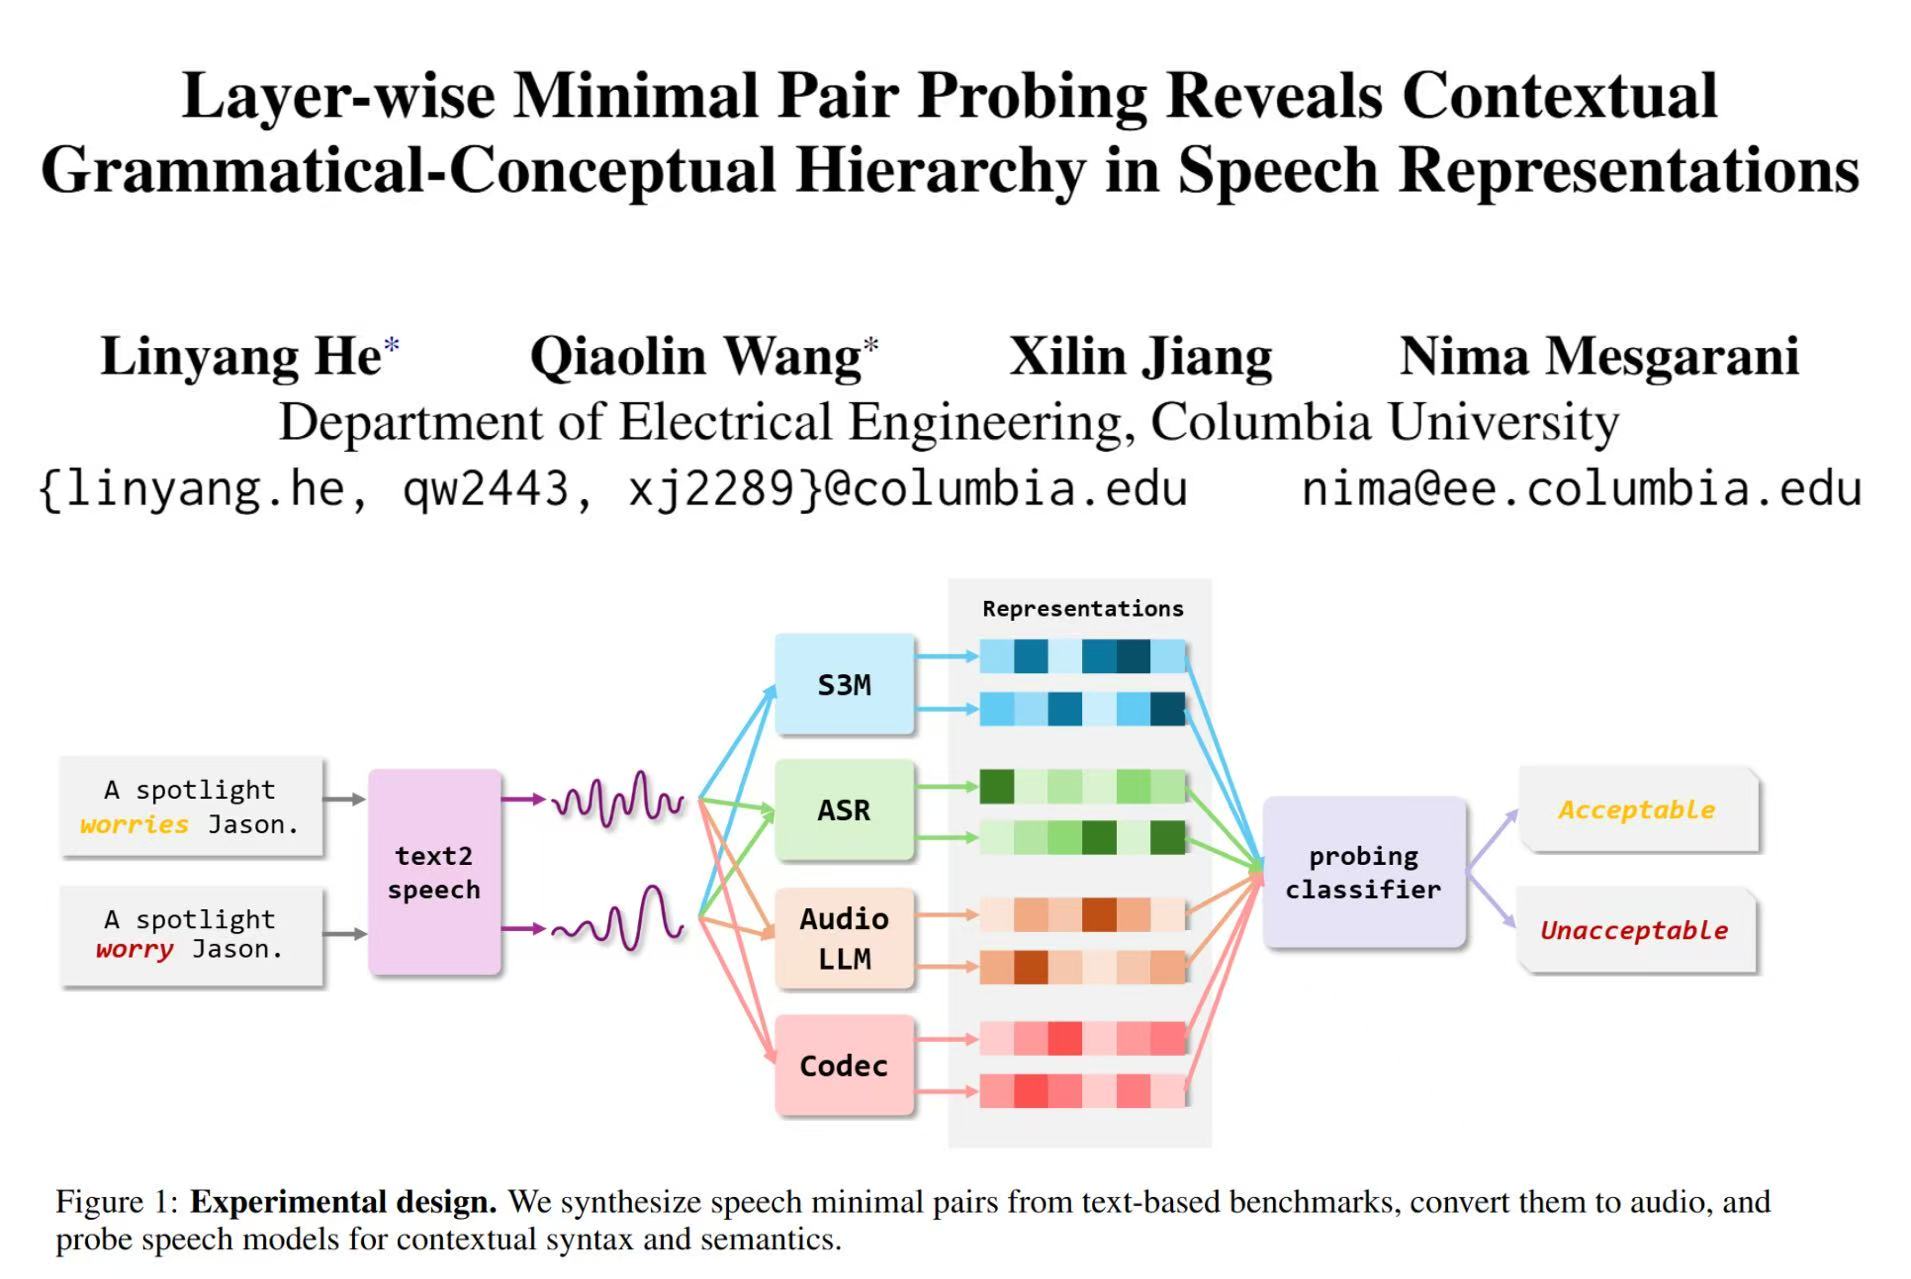 Layer-wise Minimal Pair Probing Reveals Contextual Grammatical-Conceptual Hierarchy in Speech RepresentationsIn Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025Oral presentation · SAC Highlight
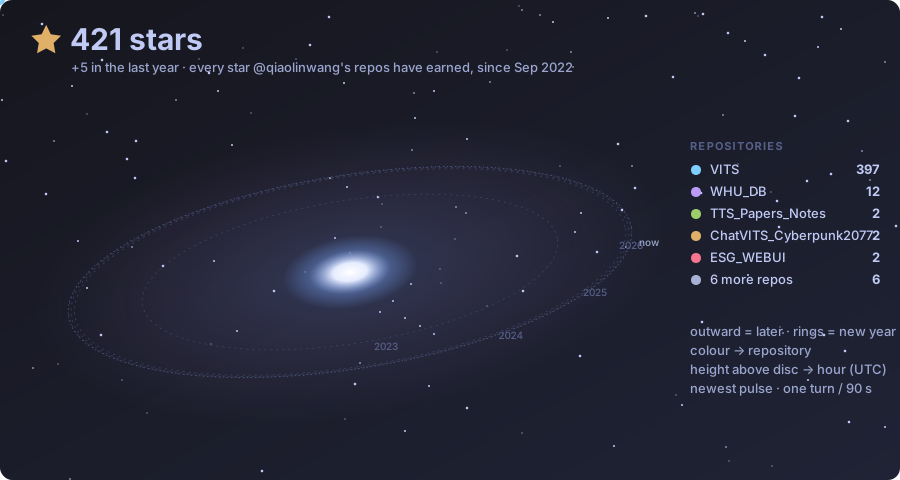
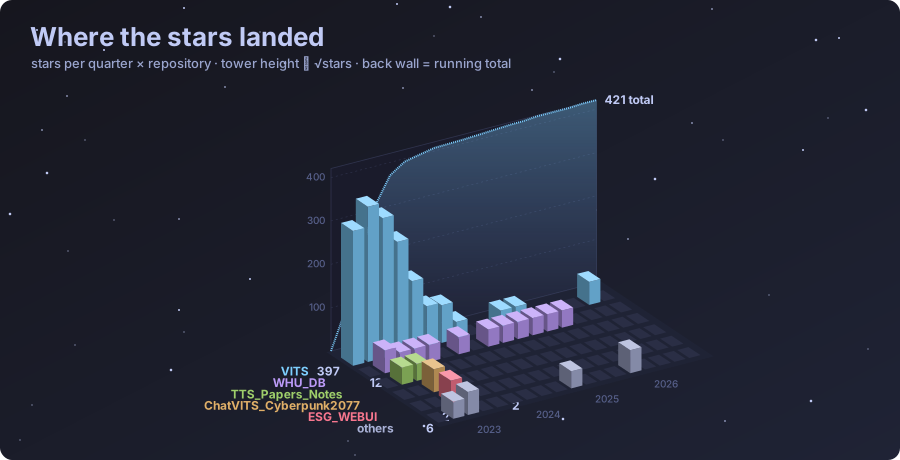
⭐ GitHub Stars in 3D


🎬 Where it started
My speech AI journey began as a side quest in 2022: teaching a model to speak as Paimon from Genshin Impact.
- Built and annotated a multi-speaker dataset of ≈48,000 clips (15 h) from 50 Genshin Impact characters, using ECAPA-TDNN for speaker classification and Whisper for transcription
- Fine-tuned a VITS speech synthesis model on a curated set of Paimon clips
- Released it as a technical demo on Bilibili (600K+ views) with a public Colab for anyone to try